Key takeaways
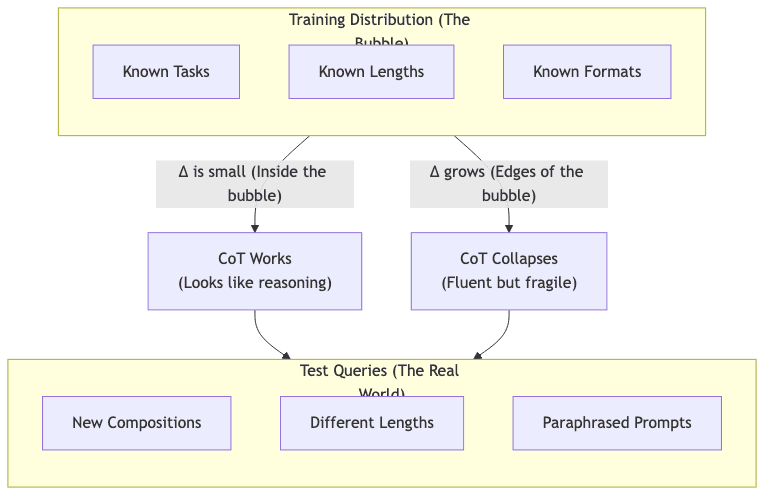
- The Dagger. The paper Is Chain‑of‑Thought Reasoning of LLMs a Mirage? A Data Distribution Lens argues that LLM “reasoning” is mostly pattern replication learned from its training data – not robust logic. The illusion shatters when you step outside the bubble.
- Three Axes of Collapse. When test data drifts even slightly off-distribution along task, length, or format axes, Chain‑of‑Thought (CoT) performance doesn’t degrade; it falls off a cliff.
- The Cleanroom. The authors build DataAlchemy, a synthetic framework that trains small LLMs from scratch. This isolates the effects of distribution shift, stripping away the confounding magic of web-scale pretraining.
- The Tell-Tale Sign. Models spit out fluent, step-by-step logic that leads to wrong answers, or stumble into right answers with broken logic. This isn’t reasoning; it’s a high-wire act. Supervised fine-tuning just moves the wire.
- The Builder’s Takeaway. Treat CoT as a user interface for the model’s latent state, not a proof of its logic. Your job isn’t to hope for reasoning, but to engineer for robustness.
Why this paper matters (and for whom)
We’ve all been seduced by Chain-of-Thought. Prompts like “Let’s think step by step” coax LLMs into producing verbose, seemingly logical traces that often lead to better answers. It’s a comforting narrative: the machine is reasoning.
If you’re building agents, copilots, or evaluators, this seductive narrative dictates your entire strategy. It determines whether you invest in more sampling and voting schemes, or in the harder work of formal verification and search. This paper takes a cold, hard look at that assumption through a data-distribution lens, and its findings should give every builder pause.
The Physics of the Problem
Let  and
 be the training and test distributions over problems and their reasoning chains. A model
 is trained to minimize error on . Its ability to generalize is bounded by a familiar, brutal truth:

In plain English: Test error is, at best, the training error plus a penalty for the reality gap between the training data and the real world. The term  measures this gap. The bigger the gap, the bigger the penalty, and the faster your performance collapses.
The punchline: The model isn’t learning to reason in the abstract. It’s learning to interpolate within the known universe of its training data. As the discrepancy grows, the eloquent chains become fluent nonsense.
DataAlchemy: A Cleanroom for Reasoning
To prove this, the authors build DataAlchemy, a synthetic world designed to perform an autopsy on failed reasoning. They strip away the mysticism of web-scale pretraining and train small models from scratch on two primitive string transformations:
- ROT(
 ): A Caesar-style character rotation.
- POS(): A cyclic shift of the string’s characters.
By composing these operations, they can create reasoning chains of any length, where every intermediate step is perfectly defined. This setup lets them probe failure modes with surgical precision.
A tiny, runnable slice
# A minimal toy demonstrating the DataAlchemy primitives.
# This is not reasoning; it's a sequence of deterministic transformations.
from string import ascii_uppercase as ABC

ALPH = {c: i for i, c in enumerate(ABC)}
REV  = {i: c for c, i in ALPH.items()}

def rot(text, n):
    """Rotate each character in the text by n positions."""
    return ''.join(REV[(ALPH[c] + n) % 26] for c in text)

def pos(text, n):
    """Cyclically shift the entire string by n positions."""
    n %= len(text)
    return text[-n:] + text[:-n] if n else text

def chain(text, ops):
    """Compose operations to create a 'reasoning' chain."""
    steps = []
    current_text = text
    for op, k in ops:
        current_text = rot(current_text, k) if op == "ROT" else pos(current_text, k)
        steps.append(current_text)
    return steps[-1], steps  # (final_answer, intermediate_steps)

# Example execution
answer, steps = chain("APPLE", [("ROT", 13), ("POS", 1)])
print(f"Steps: {steps}, Final Answer: {answer}")
# Output: Steps: ['NCCYR', 'RNCCY'], Final Answer: RNCCY
Why this matters
This controlled environment buys us two crucial things:
- We can precisely dial up the distribution shift: test on unseen compositions (task), longer chains (length), or tweaked prompts (format).
- We can dissect faithfulness: are the intermediate steps correct, even if the final answer is wrong? Or vice versa?
The Anatomy of a Collapse
1) The Illusion of Compositionality (Task Generalization)
When a model is trained on one sequence of operations (e.g., ROT -> ROT) and tested on another (e.g., POS -> POS), performance plummets.
| Train → Test (Transformations) | Scenario | Full-Chain Exact Match |
|---|---|---|
 → | In-Distribution | 100.0% |
| {, , etc.} → | Composition OOD | 0.01% |
| → | Partial OOD | 0.00% |
| → | Full OOD | 0.00% |
The takeaway: Perfect in-distribution scores mask a catastrophic failure just one step away. The model learns recipes, not principles. It often produces perfect intermediate steps followed by a garbage final answer, a hallmark of unfaithful, mimicked reasoning.
2) The Tyranny of Fixed Dimensions (Length Generalization)
Models trained exclusively on length-4 strings master length-4 problems but are useless on strings of any other length.
Text Length ( ) | Full-Chain EM | Reason Step EM | Final Answer EM |
|---|---|---|---|
| 2 | 0.0% | 0.0% | 0.0% |
| 3 | 0.0% | 0.0% | 0.0% |
| 4 (train) | 100.0% | 100.0% | 100.0% |
| 5 | 0.0% | 0.0% | 0.0% |
| 6 | 0.0% | 0.0% | 0.0% |
The model learns a specific dance for a specific rhythm. Change the beat, and it trips. Mixing in other lengths during training only helps for those specific lengths – it merely widens the bubble, it doesn’t teach the model how to dance.
3) Skin-Deep Understanding (Format Generalization)
Tiny perturbations to the prompt format – inserting or modifying a single token – can wreck performance. Changing boilerplate words is less damaging than altering tokens that define the task, but the message is clear: the model isn’t parsing abstract intent. It’s pattern-matching on surface forms.
Across all these experiments, neither model size nor sampling temperature fixed the underlying brittleness. This is not a quirk; it’s a fundamental property of the learning process.
A Map of the Mirage
The Builder’s Playbook
- Assume CoT is a UI, not an API for Truth. It’s a window into the model’s latent state, not a guarantee of logical coherence. Prefer step-verified workflows. Don’t trust; verify with code execution, symbolic solvers, or API calls. The LLM proposes; your system disposes.
- Build an OOD Gauntlet. Your eval suite must be adversarial. Systematically vary task composition, chain length, and prompt format to find the breaking points before your users do. Track both final answer accuracy and step-by-step faithfulness.
- Bake in Invariances. If an operation should be commutative or preserve length, that’s a physical law in your mini-universe. Enforce it through contrastive training, explicit checks, or rule-based filters.
- Use SFT Like a Scalpel, Not a Sledgehammer. Fine-tuning is for patching leaks in your distribution bubble, not for teaching the model abstract reasoning. Pair it with search (Tree/Graph-of-Thought), tool use, and verification to build systems that are actually robust.
- Become an Auditor of Fluent Nonsense. Develop a nose for this failure mode. When a chain reads perfectly but the answer flips under a slight paraphrase or the introduction of a distractor, you’re looking at the mirage.
A Sanity Check in 20 Lines
You don’t need huge compute to poke at these failure modes. A toy setup can reveal the core fragility.
# (A) Setup a minimal environment
python -m venv .venv && source .venv/bin/activate
pip install torch transformers datasets accelerate evaluate python-Levenshtein

# (B) Generate a tiny DataAlchemy-style dataset
# Use a script based on the Python snippet above to create train/test sets.
python make_data.py

# (C) Train a toy GPT-2 from scratch on a single task type (e.g., length-4)
python train.py \
  --layers 4 --d_model 32 --heads 4 \
  --seq_len 64 --epochs 10 --batch_size 1024 \
  --lr 3e-3 --weight_decay 1e-2 --warmup 0.1

# (D) Evaluate on out-of-distribution data
python eval.py --axis task    --id f1f1 --test f2f2
python eval.py --axis length  --train_len 4 --test_lens 2 3 5 6
python eval.py --axis format  --noise_mode insert --p 0.2
Minimal evaluation snippet (edit distance + exact-match):
import Levenshtein as L

def metrics(predictions, gold_references):
    # Assumes predictions and references are lists of strings
    em_sum = sum(1 for p, g in zip(predictions, gold_references) if p == g)
    ed_sum = sum(L.distance(p, g) / max(1, len(g)) for p, g in zip(predictions, gold_references))

    return {
        "exact_match": em_sum / len(predictions),
        "normalized_edit_distance": ed_sum / len(predictions)
    }
The Next Frontier (Or, Where the Mirage Lingers)
- Synthetic ≠ Real. DataAlchemy’s toy world is intentionally simple. The qualitative failures, however, feel uncomfortably familiar to anyone who has deployed these models in production. The core insight likely holds.
- What about modern “reasoning models”? Are RL-tuned systems that optimize for long, self-consistent chains learning to reason, or just learning to produce more convincing illusions of reasoning? This data-lens perspective predicts the same fragility at the edges.
- We Need Better Forensic Tools. Beyond final-answer metrics, we need robust, automated verifiers for intermediate steps, especially in domains where symbolic checkers are intractable.
Closing Thoughts
I read this work as a crucial reminder to separate clear articulation from correct inference. CoT gave us a window into the model’s latent space, a way for it to “show its work.” This was a massive step for interpretability and a powerful scaffold for search.
But we confused the map with the territory.
If we want models that can actually reason, we must optimize for invariance, verification, and out-of-distribution robustness – not just for more eloquent chains. The next great leap won’t come from generating more plausible prose, but from building systems that can tell when that prose is anchored in reality.
Further Reading
- Chain-of-Thought Prompting Elicits Reasoning in Large Language Models (Wei et al., 2022).
- Large Language Models are Zero-Shot Reasoners (“Let’s think step by step,” Kojima et al., 2022).
- Tree of Thoughts: Deliberate Problem Solving with Large Language Models (Yao et al., 2023).
- The authors’ DataAlchemy codebase for reproducing their experiments.